LLM Cost per Task: Are Cheap Models Really Cheap?
A lower token price looks like an easy saving. It stays a saving only if the model can finish the work without spending the difference on extra reasoning and retries.
The bill depends on the whole attempt: how much context the model reads, how long it reasons, which tools it calls, and whether you have to run the job again. A rate card gives you the price of each token. It cannot tell you how many the job will need.
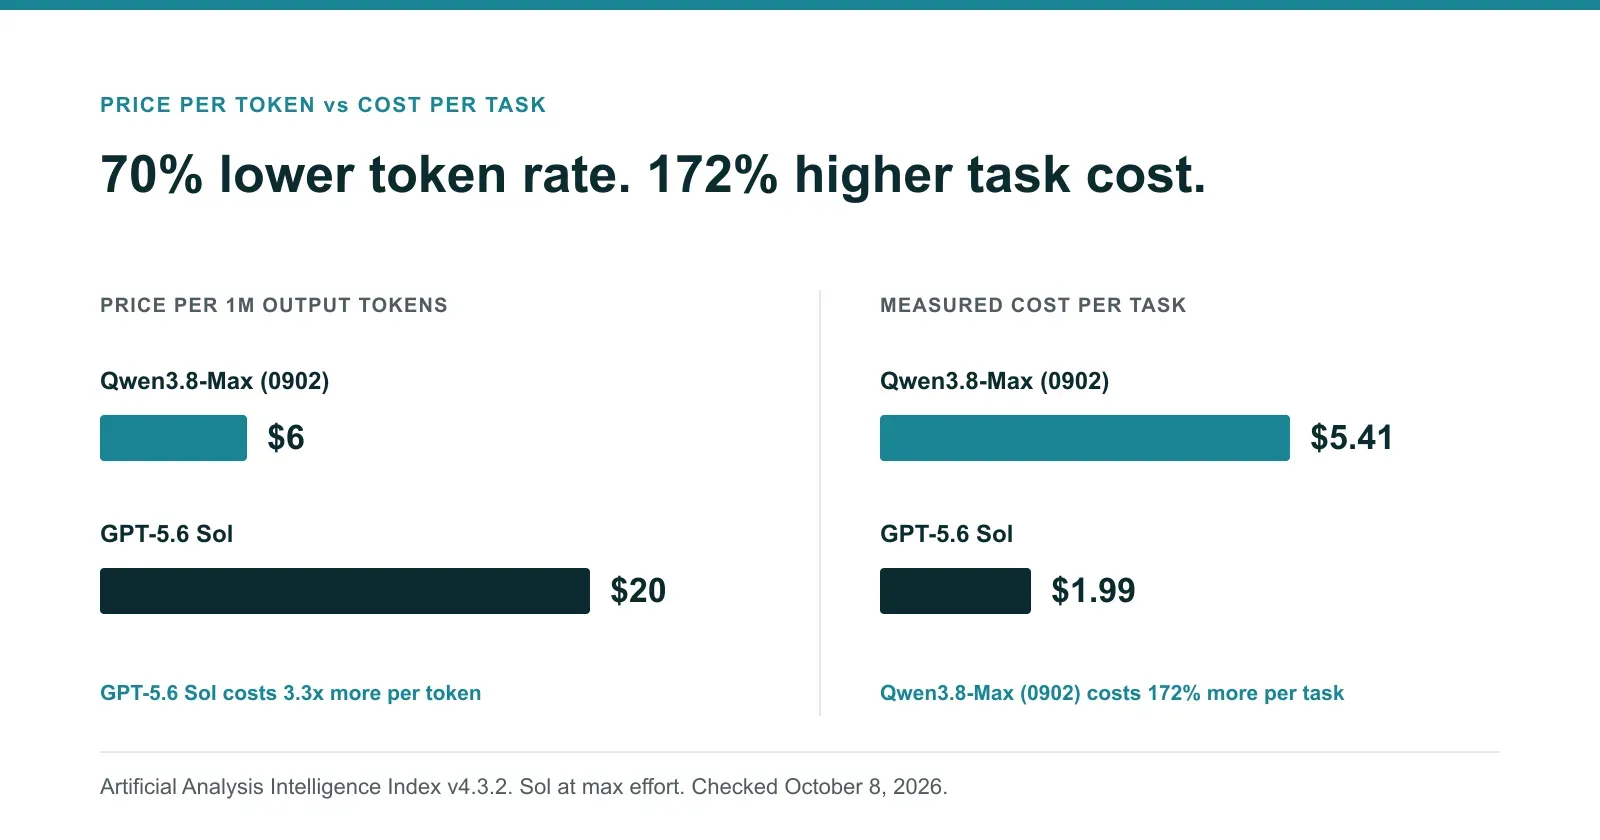
Take Qwen3.8-Max (0902) and the previous-generation GPT-5.6 Sol. Their output rates are $6 and $20 per million tokens, though Sol’s $20 is a promotional rate OpenAI lists through at least November 21, 2026. On Artificial Analysis’s current benchmark, however, Qwen costs $5.41 per task and Sol at max effort costs $1.99. At today’s prices, Qwen’s output rate is 70% lower, while its measured task cost is 172% higher.
The point is to measure how a model works through the job. Some low-price models retain a substantial cost advantage. Others consume enough tokens to lose it.
What cost per task measures
Artificial Analysis calculates a weighted average cost across its Intelligence Index evaluations. For each evaluation, it accounts for input, cache reads and writes, reasoning, and answer tokens, divides by the task count, and applies the evaluation’s index weight.
That is more useful than token price alone, but it still measures benchmark attempts. It does not divide spending by the number of results your team would accept, or include your staff’s review time.
For a model shortlist and input capabilities, use our LLM comparison. This article focuses on the bill.
The October 2026 cost snapshot
The table uses Intelligence Index v4.3.2, checked October 8, 2026, and the same models and settings as the comparison article. Rows are sorted by rounded score, highest first; ties go to the lower cost. Token prices are US dollars per million uncached input and output tokens.
We show the highest published effort, or the single published reasoning row where no effort is named. The snapshot adds Claude Haiku 5.5, released October 7, and the public preview of Mistral Large 4. Two existing rows also have new task costs: Sonnet 5.5, after Anthropic’s cut to its cache-read price, and Grok 4.6. Google announced Gemini 4 Argon on September 30 and has so far limited access to trusted cyber defenders and testers. It appears at the only setting Artificial Analysis publishes, at Google’s introductory rates. These are reference settings; the largest effort label does not guarantee the best result or establish a maximum bill.
| Model | Priceper 1M · in / out | Intelligenceindex v4.3.2 | Cost per taskbenchmark average |
|---|---|---|---|
| Claude Opus 5.5max, with fallback | $4 / $20 | 58 | $5.98 |
| Claude Sonnet 5.5max, with fallback | $2 / $10 | 56 | $5.46 |
| Gemini 4 Argonhigh, introductory pricing, limited access | $2 / $10 | 53 | $1.99 |
| GPT-6 Astramax | $10 / $50 | 53 | $3.26 |
| Claude Fable 5.1max, with fallback | $10 / $50 | 53 | $7.63 |
| GPT-6.1 Solmax | $2 / $10 | 52 | $0.72 |
| Claude Opus 5max | $5 / $25 | 51 | $5.86 |
| Claude Fable 5max, with fallback | $10 / $50 | 50 | $8.75 |
| GPT-6 Solmax | $2 / $10 | 48 | $1.04 |
| Muse Spark 1.3max, Standard pricing | $1.25 / $4.25 | 48 | $1.60 |
| GPT-5.6 Solmax | $4 / $20* | 47 | $1.99 |
| MiMo-V2.6-Propublished reasoning row | $0.435 / $0.87 | 46 | $0.13 |
| Grok 4.7xhigh | $2 / $6 | 46 | $3.74 |
| GLM-5.3max | $1.4 / $4.4 | 45 | $2.01 |
| Qwen3.8-Max (0902)published reasoning row | $2 / $6 | 45 | $5.41 |
| Grok 4.6xhigh | $2 / $6 | 44 | $1.75 |
| Kimi K3max | $3 / $15 | 44 | $2.00 |
| Claude Haiku 5.5max, prompts up to 100K tokens | $0.10 / $0.50 | 43 | $0.21 |
| GLM-5.3-Flashpublished reasoning row | $0.15 / $0.5 | 42 | $0.25 |
| GPT-5.6 Terramax | $2 / $12 | 42 | $1.40 |
| Gemini 3.8 Flashhigh, introductory pricing | $0.75 / $3.75 | 41 | $1.24 |
| Qwen3.8-Flash-Nextpublished reasoning row | $0.15 / $0.47 | 40 | $0.37 |
| DeepSeek V4.1 Flashmax, peak token rates | $0.3 / $1.2 | 39 | $0.27 |
| MiMo-V2.6-Flashpublished reasoning row | $0.14 / $0.28 | 38 | $0.06 |
| GPT-6 Lunamax | $0.10 / $0.50 | 38 | $0.07 |
| Mistral Large 4published reasoning row, public preview | $1.36 / $4.18 | 38 | $1.13 |
| Claude Sonnet 5max | $2 / $10 | 38 | $5.09 |
| GPT-5.6 Lunamax | $0.2 / $1.2 | 37 | $0.18 |
| DeepSeek V4 Pro 0813max, peak token rates | $1.32 / $3.96 | 36 | $0.67 |
The table uses provider rates recorded by Artificial Analysis, including Standard pricing for Muse and peak token rates for DeepSeek. Cached input, time-of-day discounts, batch processing, long prompts, and tool fees can change your bill.
Three rows carry a time-limited price. Gemini 3.8 Flash’s $0.75 / $3.75 is introductory through December 31, 2026 and rises to $1.50 / $7.50 on January 1, 2027. Gemini 4 Argon’s $2 / $10 is introductory with no end date announced, and Google says $4 / $20 applies afterward. The asterisk on GPT-5.6 Sol marks a promotional rate: OpenAI lists $4 / $20 at least through November 21, 2026. Mistral Large 4 appears at its list rates, although Mistral took 50% off for two weeks from its October 6 launch. Claude Haiku 5.5’s rates apply only to prompts up to 100,000 tokens; a longer prompt pays $0.50 / $2.50 on the whole request. Check the provider terms for the requests you will send; MindsHub’s rate card is separate.
GPT-6 Sol and Luna: lower rates and measured task costs
OpenAI’s new Sol and Luna releases cut the price of each token. Sol costs $2 input / $10 output per million tokens, half the promotional $4 / $20 for GPT-5.6 Sol. Luna costs $0.10 / $0.50, versus $0.20 / $1.20 for GPT-5.6 Luna.
Artificial Analysis now measures Sol at 48 and $1.04 per task, against 47 and $1.99 for GPT-5.6 Sol. Luna scores 38 at $0.07, against 37 and $0.18 for GPT-5.6 Luna. All four use max effort. These are new measurements, not the old task costs multiplied by a price cut. The opening example remains a comparison with the previous-generation Sol.
OpenAI released GPT-6.1 Sol on September 29 in its API as gpt-6.1-sol, listed at $2 input / $10 output per million tokens for prompts up to 272K input tokens, with higher rates above that. Artificial Analysis’s entry scores 52 at $0.72 per task at max, at the same $2 / $10 list rates as GPT-6 Sol, though its cached input costs $0.10 per million instead of $0.20. That is about 31% below GPT-6 Sol’s measured task cost. Artificial Analysis’s cost breakdown shows where the saving came from: input cost per task falls from $0.73 to $0.34, almost all of it in cache reads (from $0.51 to $0.12: half the price, on about half as many cached tokens), while output cost rises from $0.31 to $0.38, because its weighted output per benchmark task is about 23% higher (about 38k tokens against 31k) at the same $10 rate.
Claude Haiku 5.5 and GPT-6 Luna: same rates, different bills
Claude Haiku 5.5 and GPT-6 Luna list identical token rates: $0.10 per million input tokens and $0.50 per million output tokens. At max effort, Artificial Analysis measures Haiku 5.5 at 43 and $0.21 per task, and Luna at 38 and $0.07. The same token rates produce three times the benchmark cost.
The difference is how many tokens each model uses. Haiku 5.5 writes about 162k output tokens per task at max, against about 50k for Luna, and re-reads about three times as much cached context. Artificial Analysis’s breakdown puts its input and cache cost at $0.13 per task against $0.04, and its output cost at $0.08 against $0.03. It also scores five points higher, so the useful question is whether those points change the results you accept. Effort narrows the gap: Haiku 5.5’s xhigh row scores 41 at $0.12, and its high row scores 38 at $0.08, level with Luna at max for about the same cost.
Anthropic’s $0.10 / $0.50 also applies only to prompts up to 100,000 tokens. A longer prompt pays five times as much on the whole request, and cached tokens count toward that limit, so long-context work needs its own estimate.
Where the newer low-cost models fit
MiMo-V2.6-Pro reaches 46 at $0.13 per benchmark task, using the rates recorded by Artificial Analysis. DeepSeek V4.1 Flash reaches 39 at $0.27. GLM-5.3-Flash reaches 42 at $0.25, while Qwen3.8-Flash-Next reaches 40 at $0.37. MiMo-V2.6-Flash reaches 38 at $0.06, level with GPT-6 Luna’s 38 at $0.07. Artificial Analysis calls it slower than average and very verbose, so its low task cost comes from its $0.14 / $0.28 rates, not from short answers. These are useful candidates for a budget evaluation, especially when their supported input types match the work.
Two details keep the comparison honest. First, a model name can hide a release change: the current Qwen3.8-Max (0902) row scores 45 at $5.41, while the older 0803 row had different measurements. Flash-Next is a separate model, not a lower effort setting. Second, this is a new DeepSeek checkpoint. The older V4 Flash task cost does not describe V4.1 Flash, even when an API alias moves to the new version. V4 Pro remains available separately. See the DeepSeek section of the comparison for the current routing details.
A new version can change the bill without changing token prices
Grok 4.7 and Grok 4.6 both list $2 input / $6 output per million tokens. At xhigh, their task costs are $3.74 and $1.75, respectively. The newer model scores 46 against 44, but costs more than twice as much per benchmark task. Its launch announcement describes changes aimed at longer coding and knowledge-work tasks; test whether those changes improve the results you accept.
Opus 5.5 offers a different comparison. Its $4 / $20 token rates are 20% below Opus 5’s $5 / $25, while its max-effort task cost is about 2% higher: $5.98 against $5.86. Its score rises from 51 to 58. The 5.5 result includes the default fallback, so record that configuration with the comparison.
Sonnet 5.5 shows how little of a token discount can reach the bill. Its $2 / $10 rates are half Opus 5.5’s, but its max-effort task cost is only about 9% lower: $5.46 against $5.98. It scores 56 against 58. Both results include the default fallback.
A cache-read price can move the bill on its own
On October 7, Anthropic halved Sonnet 5.5’s cache-read price, from $0.20 to $0.10 per million tokens, and left its input and output rates unchanged. Artificial Analysis’s measured task cost fell from $7.62 to $5.46 at the same score of 56. Cache reads still account for about $2.21 of that, because agentic tasks re-read a growing context at each step. If your workload caches heavily, compare cache-read prices as carefully as the headline rates.
Try a lower effort setting
Grok 4.7 xhigh and high both round to 46, at $3.74 and $2.73 per task. Opus 5.5 max scores 58 at $5.98; high scores 54 at $1.82. GPT-6 Astra max scores 53 at $3.26, against 52 and $2.31 at xhigh. GPT-6.1 Sol max scores 52 at $0.72; high scores 50 at $0.32.
Sonnet 5.5 makes an especially large move: max scores 56 at $5.46, xhigh scores 52 at $2.01, and high scores 47 at $0.88. The cheaper setting gives up measured capability, so judge the saving against your acceptance criteria.
Those tradeoffs give you a useful experiment: run your tasks at both settings. Keep the extra reasoning where it improves accepted results, and lower it where it only adds time and cost.
Read discounted tiers as contracts
Gemini 4 Argon is the clearest recent case. Artificial Analysis scores it 53 at $1.99 per task. GPT-6 Astra also rounds to 53, though Argon is just below it before rounding. That cost uses Google’s announced introductory rates of $2 / $10. Google says $4 / $20 applies afterward. At those rates the same run costs $3.98, about 22% more than Astra’s $3.26 at its list rates.
Both of Argon’s introductory rates are 80% below Astra’s, yet it averages about 62k output tokens per task against about 27k, so its introductory task cost is 39% lower, not 80%. The saving comes from the token price, not from using fewer tokens. GPT-6.1 Sol has the same $2 / $10 rates and costs $0.72 per task. As of October 8, access is limited to trusted cyber defenders in Google’s Fairwind Program, with no date for wider access. Artificial Analysis lists a single setting, high, so there is no measured cheaper effort level to compare. Check access and billing terms before planning around Argon’s price.
Meta’s Muse Contributor option charges $0.10 per million input tokens and $0.20 per million output tokens in exchange for permission to use prompts and completions in training. That can change which data you are allowed to send. The $1.60 Muse result above uses Standard pricing; it is not a measured Contributor result.
DeepSeek’s peak, off-peak, and cache rates are another reason to record billing conditions with an evaluation. A discount matters only when your actual requests qualify for it.
MindsHub free tier
The MindsHub free tier includes selected models at no charge. Currently included: the MindsHub Air model and Jev. No credit card is required; fair use and daily rate limits apply.
Measure the cost of results you can use
Start with ten representative tasks as a pilot. Include the documents, instructions, and tool access the model will have in practice, along with a few cases you know are difficult.
- Set acceptance criteria before running the models. For extraction, that might mean every required field is correct. For a code change, it may mean the tests pass and a reviewer accepts the patch.
- Run two or three candidates. Record the model version, reasoning setting, prompts, and billing conditions. Repeat tasks where inconsistent results would matter.
- Count the whole workflow. Include failed attempts, retries, tool charges, and any follow-up model calls. Record human review time separately so a cheap but demanding model does not appear free to operate.
- Divide total spend by accepted results. If you spend $12 across all attempts and accept eight results, the cost is $1.50 per accepted result. If none pass, the model has not established a usable cost for that workflow.
Ten tasks can reveal a large mismatch; they cannot establish a dependable success rate. Expand the evaluation before a consequential rollout, using the process in our model selection guide.
Re-run it when the model, alias, prompt, or pricing changes. Keep the evaluation set and scoring rules outside any one agent workspace; the workspace migration checklist covers the context and workflow details to preserve.
MindsHub Agents provides a workspace with a choice of models and Anton, an open-source agent harness. MindsHub Inference gives developers access to the MindsHub model catalog through one API. Check model availability and MindsHub pricing for the service you plan to use.